
Have OpenAI or Anthropic billing exports?
Analyze your AI spend
Upload billing CSVs to see trends, anomalies, model mix, cached-token behavior, and forecast direction. No account or code required.
Analyze billing exportsCustomer usage control for B2B AI products
Track AI usage by customer. Set allowances, enforce limits, and enable PAYG.
Hard limits, forecasts, and confirmed email or Slack anomaly alerts are included with Meter.
100,000 usage events free each month · No card required · Includes $10 starting credit
Connect Claude, ChatGPT, or your own agent via MCPMeter connects the dots
Attribute each call, token, agent action, or custom event to the right customer.
Apply allowances and limits before expensive AI work runs.
Get email or Slack alerts when usage or spend breaks from its learned baseline.
When seats stop measuring usage
One customer can launch dozens of agents, automations, and background workflows without adding a single seat. UsageTap connects that machine work to the customer account, so you can include usage, charge overages, or enforce limits.
Illustrative customer scenario
Margin at risk10 paid seats
Revenue is tied to ten people.
40 agents launch
Automations run without creating new seats.
8× more AI work
Provider cost grows while seat revenue stays flat.
Usage becomes billable
Attribute work to the account, bill it, or limit it.
Wrap existing LLM calls or report custom usage. Track OpenAI, Anthropic, Google, OpenRouter, self-hosted models and API workloads against the same customer usage record.
Free evidence-first tools
Choose the path that matches the evidence available today. Each starts useful and keeps account creation optional.
Have OpenAI or Anthropic billing exports?
Upload billing CSVs to see trends, anomalies, model mix, cached-token behavior, and forecast direction. No account or code required.
Analyze billing exportsCan add a small wrapper to your application?
See usage and cost from the first observed call, attributed to real application workloads.
Start live usage analysisHave an expensive or oversized prompt?
Paste one prompt and see what can be removed, what is preserved, and how many tokens you could save.
Test a promptProduction proof · FocusedFit.ai
FocusedFit.ai implemented UsageTap to attribute AI usage to customers and support plans, limits, and billing. Within about a week, production visibility helped uncover a cache-breaking instruction, a silent data-truncation bug, and duplicated context.
Representative production calls
After fixing the application
So the team left it off
UsageTap for AI agentsMCP
Connect Claude, ChatGPT, Codex, or your own MCP-compatible agents and workflows to review customer allowances, spot unusual usage, and compare recorded AI costs.
Requires a UsageTap account. Read-only access: the connection cannot change plans, contact customers, or modify account data.
Try asking your agent
Answers use the customer and usage data recorded in your UsageTap account.
Monitoring and control · Included with Meter
UsageTap Guard
API usage shifts toward exports. LLM output sizes change. Guard compares reported application behavior to help investigate significant changes that may indicate misuse or runaway work, even when totals stay steady.
Comparisons need enough usable history. Organization admins inspect saved evidence; a finding is a reason to investigate.
Spend protection
Configured allowances and limits enforce policy when your application checks them before work begins. Forecasts show where usage is heading; general anomaly alerts flag confirmed usage or spend anomalies.
Usage or spend spikes: A new workflow may be taking off—or an automated process may be running away.
Budget burn accelerates: Projected month-end spend may be crossing the budget your team configured.
A customer nears a limit: A hard boundary can stop known overages before expensive work begins.
Provider-reported spend is authoritative daily; metered calls add faster hourly estimates.
See how spend protection works →Email and Slack notifications are opt-in and default off. Alerts support investigation; configured Meter limits enforce policy separately. Guard does not automatically block activity.
Customer-facing usage
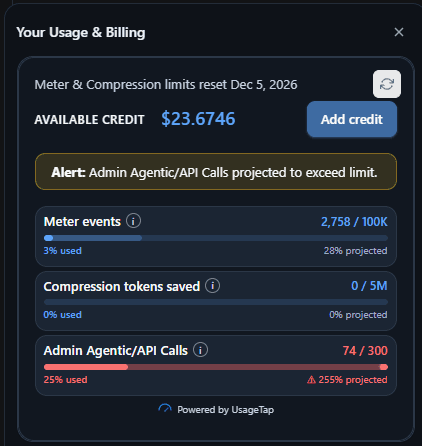
Put current consumption, remaining allowance, forecast, and plan status inside your product. Customers can act before a limit or invoice becomes a surprise.
Point Codex, Claude Code, Cursor, or Copilot at the UsageTap integration guide. It will locate your provider calls, preserve your existing SDK, add customer attribution and pre-call policy checks, and run the relevant tests.
UsageTap Compress
Compact structured context during model calls or turn reusable source material into smaller, task-ready context—with checks for the facts, values, structure, and behavior that must remain.
Deterministic first · Editable Quality Checks · Original-input fallback for Runtime
Separate JSON and long-text benchmarks · Evidence through November 9, 2026
TL;DR: strong JSON savings with correct answers; long text benefits from selective compression, with observed quality limits. Cost savings below include compression fees.
10 existing tasks / 9 source inputs · Revalidated separately
30/30 full-service answers correct. All 30 transformed representations reconstruct the original data exactly.
Already minified? Another 16.4% fewer context tokens and 3.7% net cost saving.
100 expanded tasks / 97 contexts · Aggressiveness 0.50
Across all 100 tasks, including 56 guard fallbacks and 1 policy skip: 8.1% fewer context tokens and 4.9% lower modeled cost overall.
106/109 candidate answers correct on resolved accepted comparisons vs 109/109 original controls. Three corroborated regressions across two news questions; 20/129 accepted comparisons remain unresolved.
Correct answers are the primary outcome. Source damage helps explain errors or fragility; damaged wording with a correct answer is not an observed answer regression.
Knowing what not to compress matters. Some inputs should stay uncompressed to preserve required information. JSON skipped the lossy model stage on all 10 inputs and kept its structural savings. Long text returned 56 guard fallbacks and one policy skip. In targeted gentler follow-ups, preserving the Mali source produced three correct repeated answers at each setting.
JSON and long text have separate denominators and no pooled savings average. Long-text accepted-input averages include quality failures and exclude fallbacks/skips; overall results include every decision. Each cohort uses three answer repeats with GPT-6.1 Terra at medium reasoning. JSON retains the original 120 answers across four conditions: both newer Terra-low and Sol-low reviewers agreed they were correct, using 22 review calls including calibration. No new JSON compression or answer generation occurred. Long text covers 20 tasks each from HotpotQA, MultiNews, MuSiQue, Qasper and QMSum.
Gentler follow-ups on the two selected news cases produced 6/6 correct candidate answers per setting at 0.30, 0.25 and 0.15. Accepted VX cost savings were 7.2%, 6.6% and 2.1% respectively; Mali returned original text. These are exploratory results, not a new 100-task result or a proven safe default. Recorded guard reasons do not establish 57 proven errors prevented. An additional declining pair on identical preserved input is generation variation, not verified compression-caused loss.
Frozen API rates dated November 8, 2026 price application prompts, measured answer output and compression fees, with cold input and no remaining free compression allowance. These are API-equivalent scenarios, not subscription invoice savings. Offline review overhead is separate. The tested forced model-assisted long-text setting differs from the product’s deterministic-first default.
GPU resources for training and benchmarking can be hard for startups to access. We’re grateful to the Google for Startups Cloud Program for welcoming UsageTap as a member and helping make benchmark hosting possible. Membership does not imply Google’s endorsement of UsageTap or these results.
Simple prepaid pricing
Meter included
100,000 usage events free every month, then graduated rates from $0.20 to $0.05 per 1,000
Compress included
5M real-time tokens saved free every month
Easy to start
No card required, plus $10 in starting credit and no automatic paid subscription
Plan with your own numbers
Test included usage, overage rates, and margin using your own cost and customer assumptions.
Simulate a usage planChoose a usage unit
Plan your AI economics
Free, vendor-neutral worksheets for launching a product or adding AI to one you already run.
Ten practical checks for founders and builders planning a new AI product, free trial, or rapid launch.
Download the startup guidePDF · 24 pages · No signup required
Ten practical checks for product, engineering, finance, and commercial teams adding AI to an established application.
Download the existing product guidePDF · 26 pages · No signup required
Want to discuss your plan? Book a 30-minute application readiness review.
Book a readiness review →Start tracking AI usage by customer, apply plan limits, and send trusted usage to Stripe.